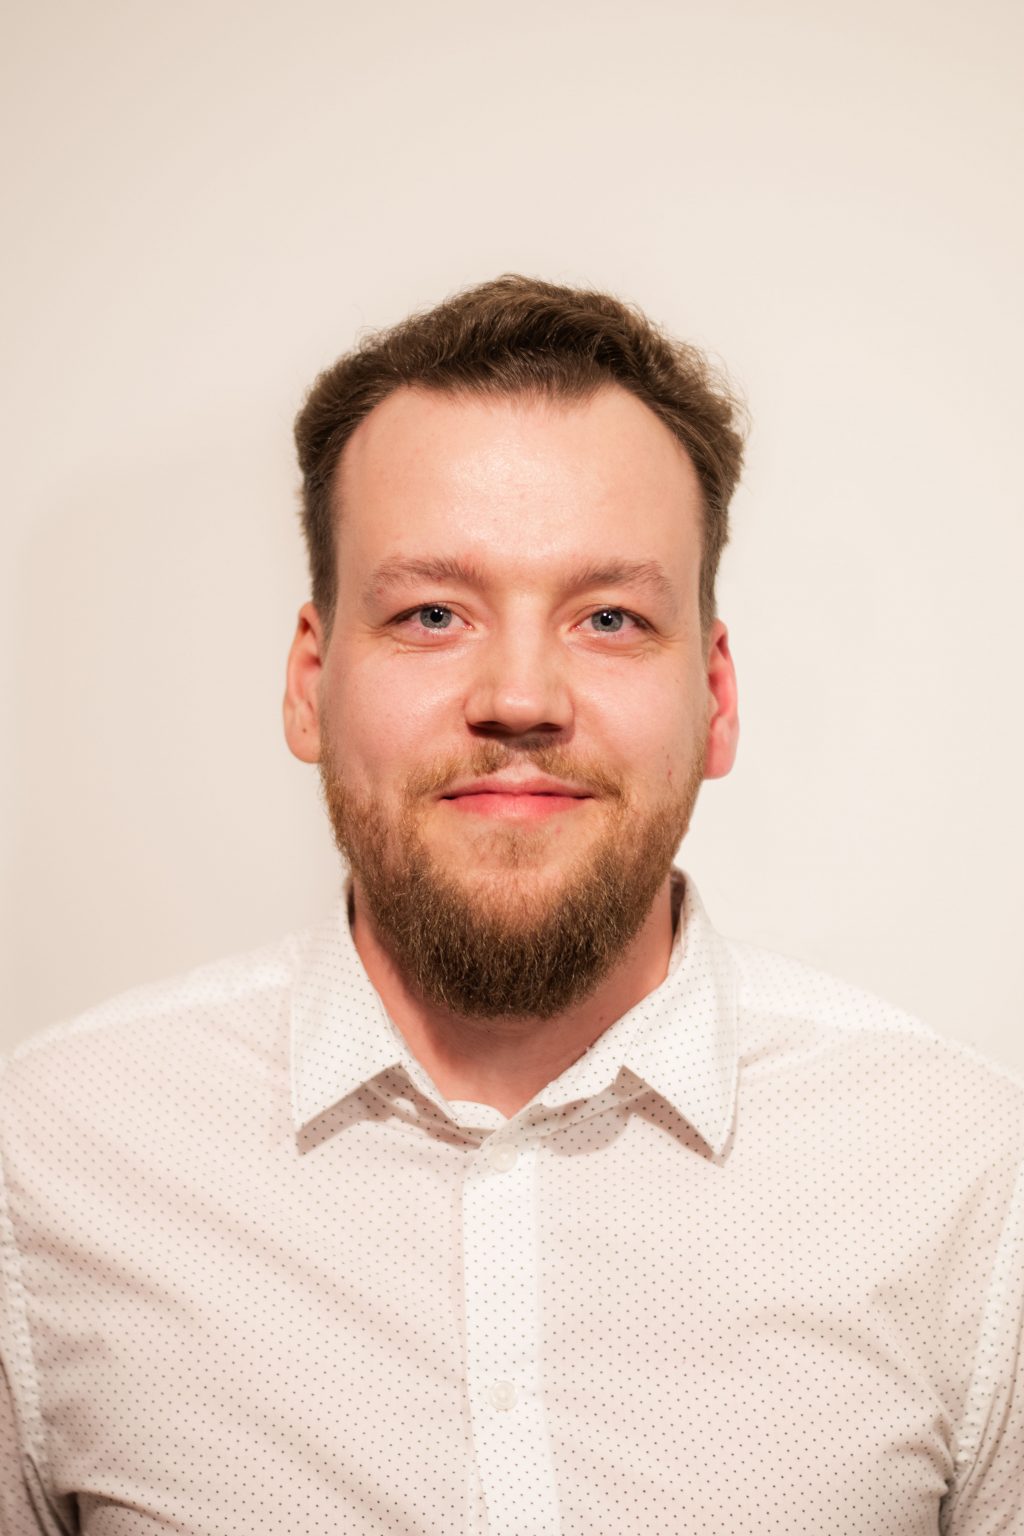
Jānis Ārents
Ph.D.
Senior Researcher
Researcher Janis Arents has been working in EDI since 2016. In 2023, he obtained the degree of Doctor of Science (Ph.D.) in the branch "Engineering and technologies: electrical engineering, electronics, information and communication technologies" at Riga Technical University - RTU, (Riga, Latvia). Main research topics are connected with innovative digital technology usage in industrial applications, including computer vision and artificial intelligence-based systems for industrial process automation, and mobile robot systems. Actively involved in EDI robotics field development. Main expertise and interests in areas such as industrial robotics, mobile robotics and their control systems; ROS; ROS2; 3D modelling; artificial intelligence, automation, cyber-physical systems.
Projects
1 result
Publications
- 2025
Correction to: Towards Open-Set NLP-Based Multi-Level Planning for Robotic Tasks(opens in a new window)
Peteris Racinskis, Oskars Vismanis, Toms Eduards Zinars, Janis Arents, Modris Greitans
Applied Sciences (Switzerland), Vol. 15 (5), MDPI
Abstract
In the original publication [1], there was a mistake in Table 1 as published. The column data in the table are reversed. The corrected Table 1 appears below. The numbers in the Abstract referring to Table 1 were mismatched. A correction has been made to the Abstract. From “while the semantic maps exhibit maximum recall rates of 94.69% and 92.29% for the 2.5d and 3d versions, respectively.” To “while the semantic maps exhibit maximum recall rates of 92.29% and 94.69% for the 2.5d and 3d versions, respectively.” The statements in the Discussion section citing Table 1 were mismatched. A correction has been made to the Discussion Section, Paragraph 5: From “For the static depth map, using ternary embedding values appears to paradoxically result in slightly improved recall—though this peculiarity is likely to disappear with larger and more varied data sets. With the vectree map, the same output set was produced by 32-bit and 8-bit embeddings, with two otherwise recalled observations being missed (one each of “white bottle” and “energy drink bottle”) and one otherwise missed observation being recalled (“pink foam”).” To “For the vectree map, using ternary-embedding values appears to paradoxically result in slightly improved recall—though this peculiarity is likely to disappear with larger and more varied datasets. With the static depth map, the same output set was produced by 32-bit and 8-bit embeddings, with two otherwise recalled observations being missed (one each of “white bottle” and “energy drink bottle”) and one otherwise missed observation being recalled (“pink foam”) with ternary embeddings.” The authors state that the scientific conclusions are unaffected. This correction was approved by the Academic Editor. The original publication has also been updated. © 2025 Elsevier B.V., All rights reserved.
- 2025
Model Selection and Prompting Strategies in Resource Constrained Environments for LLM-based Robotic System(opens in a new window)
Toms Eduards Zinars, Oskars Vismanis, Peteris Racinskis, Janis Arents, Modris Greitans
Charting the Intelligence Frontiers Edge AI Systems Nexu, p. 147-165, River Publishers Series in Communications and Networking
Abstract
Large Language Models (LLMs) are increasingly becoming adopted for various applications in information processing and content generation. Coupled with the diverse availability of model weights, quantization, and fine-tuning, it is desirable to find the best-performing LLM within a certain memory budget. Prompting strategy plays a similarly major role in the quality of generation, with various methods existing that attempt to induce desired behaviour, requiring a major time investment to develop. As new models with better performance to memory ratio become available, it may be tempting to implement them into an existing system for potential performance improvements. In this work we explore the process of changing weights and note that weights from larger models or of different quantization precision are unable to replace the original model without modifications to the prompt contents, which in turn implies complications in developing modular, weight agnostic Systems.
Indexed in Scopus / WoS
- 2025
The EDI Multi-Modal Simultaneous Localization and Mapping Dataset (EDI-SLAM)(opens in a new window)
Peteris Racinskis , Gustavs Krasnikovs, Janis Arents and Modris Greitans
Data, Vol. 10 (1), p. 5, MDPI
Abstract
This paper accompanies the initial public release of the EDI multi-modal SLAM dataset, a collection of long tracks recorded with a portable sensor package. These include two global shutter RGB camera feeds, LiDAR scans, as well as inertial and GNSS data from an RTK-enabled IMU-GNSS positioning module—both as satellite fixes and internally fused interpolated pose estimates. The tracks are formatted as ROS1 and ROS2 bags, with separately available calibration and ground truth data. In addition to the filtered positioning module outputs, a second form of sparse ground truth pose annotation is provided using independently surveyed visual fiducial markers as a reference. This enables the meaningful evaluation of systems that directly utilize data from the positioning module into their localization estimates, and serves as an alternative when the GNSS reference is disrupted by intermittent signals or multipath scattering. In this paper, we describe the methods used to collect the dataset, its contents, and its intended use.
Indexed in Scopus / WoS · Scopus percentile: 69 · SNIP: 0.857
- 2025
Multi-Step Object Re-Identification on Edge Devices: A Pipeline for Vehicle Re-Identification
Tomass Zutis, Peteris Racinskis, Anzelika Bureka, Janis Judvaitis, Janis Arents, and Modris Greitans
Charting the Intelligence Frontiers – Edge AI Systems Nexus, p. 233-253, River Publishers
Abstract
In modern computer vision tasks, the ability to identify and track objects across different scenes and environments has become important for numerous applications, especially in transportation. Inspired by this need, we propose a method that leverages a multi-step process focused on extracting and using object features for object re-identification. The proposed pipeline includes the following steps: detecting an object, converting its features into a vector embedding, storing this embedding in a vector database, and then querying the database to find the same or similar objects based on their feature embeddings. This approach enables us to identify the same object across different images or cameras, even in varying locations. This is essential in scenarios like Vehicle Re-Identification. For such scenario, implementing this process on edge devices is crucial. Therefore, ways to tailor the pipeline and its outputs for edge devices are outlined. The paper details the pipeline’s structure along with the experimental setup demonstrating its application, particularly in vehicle re-identification. The pipeline achieves 70-80% re-identification precision when dealing with vehicle images from our network cameras and above 70% Rank-1 accuracy when dealing with a CityFlow video track scenario.
- 2024
Towards Open-Set NLP-Based Multi-Level Planning for Robotic Tasks(opens in a new window)
Peteris Racinskis , Oskars Vismanis , Toms Eduards Zinars , Janis Arents and Modris Greitans
Applied Sciences, Vol. 14 (22), p. 10717, MDPI
Abstract
This paper outlines a conceptual design for a multi-level natural language-based planning system and describes a demonstrator. The main goal of the demonstrator is to serve as a proof-of-concept by accomplishing end-to-end execution in a real-world environment, and showing a novel way of interfacing an LLM-based planner with open-set semantic maps. The target use-case is executing sequences of tabletop pick-and-place operations using an industrial robot arm and RGB-D camera. The demonstrator processes unstructured user prompts, produces high-level action plans, queries a map for object positions and grasp poses using open-set semantics, then uses the resulting outputs to parametrize and execute a sequence of action primitives. In this paper, the overall system structure, high-level planning using language models, low-level planning through action and motion primitives, as well as the implementation of two different environment modeling schemes—2.5 or fully 3-dimensional—are described in detail. The impacts of quantizing image embeddings on object recall are assessed and high-level planner performance is evaluated using a small reference scene data set. We observe that, for the simple constrained test command data set, the high-level planner is able to achieve a total success rate of 96.40%, while the semantic maps exhibit maximum recall rates of 94.69% and 92.29% for the 2.5d and 3d versions, respectively.
Indexed in Scopus / WoS · Scopus percentile: 79 · SNIP: 0.924